Showing posts with label linux. Show all posts

TIP: Screen -- Persistent Terminal Sessions in Linux

If there is one thing I learned in Linux that makes life extremly easy, I would say it is the possibility (or ability) to maintain persistent terminal sessions. This tool comes in handy when working remote and working with servers in particular. Imagine if you are uploading a sosreport or uploading huge core dumps as supplement attachments for a support ticket, and your shift ends. Would you want to wait another couple of hours for the upload to finish? Or, would you want to have a persistent terminal session so that your uploads are thugging along while you drive home?

I'm quite sure the answer is obvious. Linux has this utility called "screen". Screen allows the user a persistent shell session, at the same time multiple tabs for the same connection. It also allows the user to disconnect and re-connect at will, which is really handly for remote users or if for some reason the network connection gets interrupted. Another benefit is for users to simultaneously connect to the same screen session.

This utility is not installed by default. In Ubuntu, to install simply run [sudo apt-get -y install screen].

To run screen, simply run [screen]. You might notice that nothing much has changed upon execution, but running [screen -ls] shows a session is already running. This is how plain it looks (I scrolled it back 1 line just to show you I ran screen).
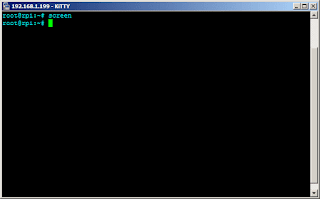
Screen Without .screenrc

You can change this behaviour by making modifications to the screen startup configuration. It is a file named ".screenrc" that is placed in the home directory of the active user. This file does not exist by default and needs to be created by the user himself/herself.

I have created my own ".screenrc". It is available in github at this link: https://github.com/dillagr/dotfiles.

A few notes regarding the configuration. It alters the default behaviour of screen. The control command or escape command which is [CTRL]+[A] by default -- modified to [CTRL]+[G]. Meaning, any other hot-key for screen is preceded by a [CTRL]+[G] then [C] for example to create another tab (or create another window); [CTRL]+[G] then [D] to detach from screen.

Shown below is how it looks on my Raspberry PI. See any notable difference(s) compared to the previous screenshot?

Screen With .screenrc

The other thing that is most notable about this configuration is that you will see the number of tabs at the bottom, the hostname of the server at the lower left corner and the current active tab. This way it is really clear that the terminal is running an active screen session. Scrollback is set to 1024 lines. That way you can go back 1024 lines that are already off the screen. You may customize this as well.

 RELATED: Install Adblock on Raspberry Pi via Pi-Hole

Having screen and a persistent terminal session is one of the best tools for a system administrator.. But as I will show you soon, it is not limited to administering servers. Stay tuned.

Share:

HOW-TO: Errors Updating PiHole DNS Cache

I personally use pihole to block ads, phishing and malicious websites (more leaning toward the latter), from access in my home network. This software can be easily setup on a Raspberry PI, and a little knowledge about good ol' Linux. On my setup I use pihole in tandem with the DietPI operating system (kudos go to Darwin Sonza for suggesting DietPI). This combo brings about faster internet access, since frequent DNS lookups are handled (and cached) by pihole at the same time dietpi limits write IOPs to the SD card, preserving its useful life.

In case you are interested in setting up your own Raspberry PI with pihole, checkout the previous post Install Adblock on Raspberry Pi via PiHole. In order to benefit further, pihole needs to be regularly updated much like dietpi. However, the recent update of pihole broke on my setup. And, here's the solution to the problem, if ever you encounter it yourself.

Just so you have an idea what the problem is or how to replicate it, I ran the command "pihole -up" to initiate a pihole update. This command ended up with the error message: "Error: Could not update local repository. Contact support."

The complete message is captured by the screenshot below, including messages prior to that error.

Error: Could not update local repository. Contact support.

If you are hit by the same message, on the command line, execute the following:
rm -R /var/www/html/admin
git clone https://github.com/pi-hole/AdminLTE /var/www/html/admin
pihole -r

After these commands are ran, you see a similar window like below.

PiHole Update Complete!

The Raspberry PI is a very useful tool in my home network. I have also used it as a PVR for downloading my favorite TV series.

 SUGGESTED: Introduction to Raspberry PI (Udemy)

Is there a better solution to the above? Or perhaps another way to solve the issue? I always am on the lookout for those. Kindly share them in the comments section below.

Share:

FAQ: Errors After Deleting SWAP Logical Volume

I was setting up CentOS7 in order to orient myself with SELinux and be comfortable with using it. If you have been an avid follower of my articles, most of the recent ones have been revolving around Ubuntu16 LTS. I really didn't prepare and think much about the requirements for the initial setup and what was required. I simply followed my intuition -- experience has always been reliable and LVM is flexible when it comes to disk requirements.

That flexibility was put into context by this recent setup. Due to missed preparations and mis-calculated assumptions, I had to modify the disk partitioning and took the easiest way out, which is to sacrifice swap. After all, performance would not be very good if a virtual machine started swapping. As it turns out, I dug myself a hole.

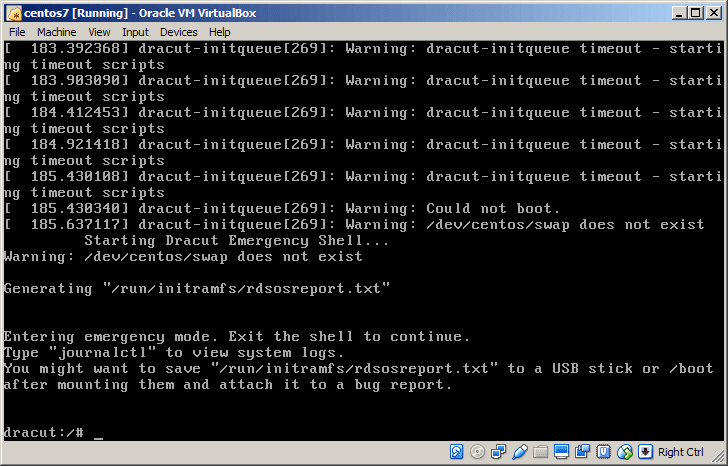
At first, the VM took a really long while to boot-up, and eventually error'ed out. The error message started with, "WARNING: Could not boot." Fortunate for me, I was able to take a screenshot to share.

WARNING: Could not boot.

Maybe I was cloning VM templates long enough that I'm entirely new to this kind of scenario. I could simply rebuild the swap logical volume and do away with the problem but "what if" I encounter this again in the future? I knew I have to know how to solve this problem (and share the solution found).

I knew that only swap was missing and Linux will work without it. So I simply pressed [CTRL]+[D] and the VM continued to boot-up. The clue to the solution was in the next message shown -- "Warning: You might want to regenerate your initramfs." So I did proceed my research this route (Assumption: maybe swap was hard-coded in initramfs).

Warning: You might want to regenerate your initramfs

To regenerate the initramfs files run "dracut --force --regenerate-all" (NOTE: You might want to take a copy of the files contained in /boot prior to executing this command). After reboot, same thing.

Most of the Google searches returned topics related to Cobbler and Kickstart.. but some of them mentioned checking /etc/grub.conf. However, grub.conf is no longer in /etc but is in /boot/grub2 and under a different name "grub.cfg". So I checked that file, and swap is in fact hard-coded in grub.cfg. And once removed, will resolve the error.

But modifying grub.cfg is dangerous. It can however, be generated using the command grub2-mkconfig and the template files are found in /etc/grub.d and the file /etc/default/grub. Modifications can be done in /etc/default/grub, then re-generate the grub configuration file and dracut command above can do the rest. The commands are shown on the screenshot of the console below.

dracut --force --regenerate-all

After these modifications the virtual machine booted, and was quick to the login prompt, if I may add. Now, I have a sandbox VM in my laptop that I could do experiments with.

 RELATED: FAQ: Cloned Linux Virtual Machine with Boot Errors

If it so happens that you deleted the swap logical volume and found yourself in the same exact scenario I was in, this is one solution. If you have any other solution(s), please share. I'm interested to learn other ways to do this.

Share:

HOW-TO: Boot to Recovery/Rescue Mode

Booting to Recovery mode or Rescue mode is important. This is primarily due to the single most important reason -- nobody can predict an impending disaster. And this is why infrastructure personnel like me have jobs.

Below I have a screenshot of one of the many reasons that you might want to boot in Recovery mode. The error being "VFS: Unable to mount rootfs on unknown-block(0,0)". The cause for this error is another topic altogether, but this error needs the intervention of a system administrator.

VFS: Unable to mount rootfs

The error can manifest on a baremetal set-up or a virtual machine. The screenshot is on an Ubuntu LTS 16.04 guest running on VMware ESXi v5.5. The guest operating system simply won't boot no matter what.

First restart and interrupt the boot process and modify some boot options. Look for the line containing "linux" and at the end of the line, append "systemd.unit=recovery.target" (NOTE: Both rescue.target and recovery.target works). Then press F10 to boot.

systemd.unit=recovery.target

Modifications above will interrupt the boot process to allow recovery mode of other installed kernel images, otherwise not shown on the boot menu. When presented with that menu, select a recent kernel image a few versions down from the current unbootable one. Make sure to select the option with "(recovery mode)" in it. Otherwise, just input the root password when on the recovery console when prompted.

On the console terminal, remove the unbootable kernel image (or force a reinstall), or execute other applicable steps/procedures to successfully boot the system. Hope this tip helps in accessing the recovery mode or rescue mode the next time a need for it arises.

 RELATED: Quantifiably Measure Boot Time Optimizations

Do you have another way to access the recovery mode? Please share it on the comments below.

Share:

TIP: Configure NGROK Tunnel with Supervisor

I use a Raspberry PI (RPI) at home. I have blogged several times about my adventures with the RPI and some automation that I programmed in. It is currently running a very lightweight and optimized version of Linux named DietPI. The RPI is cheap. It operates cheap, since it doesn't consume a lot of electricity meaning I could leave it running headless 24x7x365. The only time it reboots is if there are critical updates that require it.

Since it is running 24x7, the RPI could also serve as my SSH tunnel to my home network from the internet. I use ngrok to achieve this and forward the SSHD port to the tunnel server. Ngrok does not run in daemon-mode and the developer has expressed that this feature will not be built-into the software. But on Linux this is not a really problem.

A supervisor could handle the software and even restart it if necessary. This is how I did it on my RPI.

First, install supervisor and download the latest version of ngrok.
apt-get -y install supervisor

Download ngrok off its developer's website, https://ngrok.com/download. Choose Linux ARM. Extract the contents of the zip file and copy it to /usr/local/bin. While in the ngrok website, register and obtain an authtoken.

NGROK AuthToken

Next, generate the default ngrok configuration file by running:
/usr/local/bin/ngrok authtoken [putyourownauthtokenhere]

A configuration file will be generated in $HOME/.ngrok2/ngrok.yml. I modified this configuration file and copied it to /etc. The entire contents of my ngrok.yml is below.

NGROK Configuration ngrok.yml

On to supervisor configuration. Create the configuration file as follows:
[program:ngrok]
command=/usr/local/bin/ngrok start --all --config=/etc/ngrok.yml
autostart=true
autorestart=true
stopsignal=QUIT

Then, set supervisor to autostart at boot.
systemctl enable supervisor
systemctl start supervisor

To check the status of supervisor controlled daemons, run..
supervisorctl status

Check the dashboard on the ngrok website to see how you could connect to the tunnel from any internet connection.

 RELATED: Root Backdoor to VMware ESXi Host

The best part is: this configuration doesn't have to modify firewall configurations nor forward ports on the router.


Share:

HOW-TO: Install Adblock on Raspberry Pi via Pi-Hole

Bandwidth is a precious resource in this digital age.. This might not be the case for everyone but in the Philippines where the cost of being connected is still through the roof, this statement is still true. Couple this with the fact that people want to be connected and online, and the mix gets a bit complicated.

Studies have shown that bandwidth (or network traffic) can be minimized by using adblock technology. Thus this resource could be better utilized by more important or more significant information to be consumed by the end user, not ads. A research has shown this to be by a factor of 25% to 40% (click here for reference). That is HUGE!

With that study and its statistics, it figures that one should be minimizing network traffic or find means and ways to reduce the non-significant content -- in the form of ads. One way to do this is with the use of Raspberry Pi (R-Pi). This is in fact a very cheap way to implement adblock, and you will see it is very simple to do.

This article aims to outline installation instructions over a popular R-Pi operating system OSMC. The installation procedure for OSMC has been discussed in the previous post. There has been a series of posts involving the use of Raspberry Pi in this site.

Prior to installing Pi-Hole, it would be good to browse its documentation and have a better understanding of how it does the adblock. Click here to go there.

The installation procedure itself is pretty simple and as automated as you want it to be. Just launch a PuTTY session to the R-Pi and run the command on the banner of the Pi-Hole website -- curl -L https://install.pi-hole.net | bash (or copy-n-paste this command).

Pi-Hole Install

It is as simple as it could get. Now the only thing that needs to be done is to configure the router to assign the R-Pi as the primary DNS server when it hands out DHCP IP addresses.

Related: Setup Caching DNS Server using TreeWalk

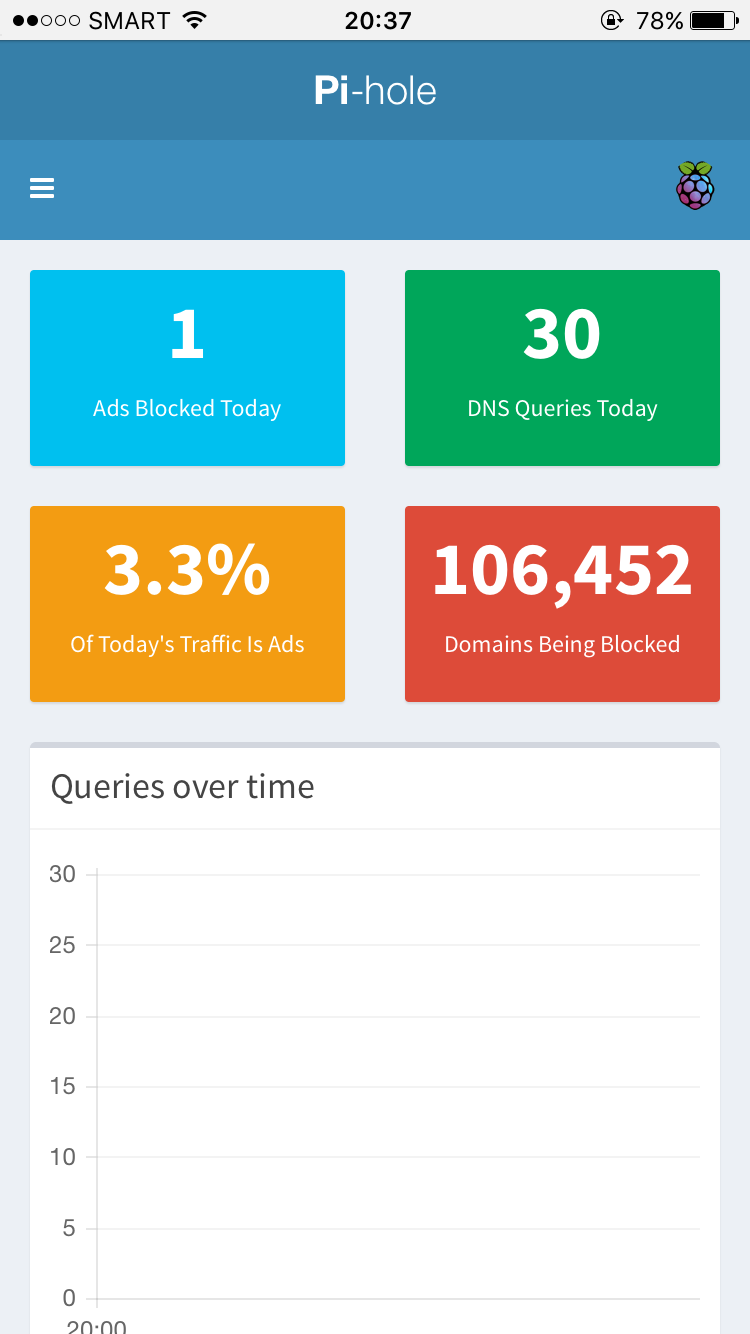
Once in a while, you may want to tickle your curiosity and find out how much traffic is blocked by Pi-Hole and you just open a browser and browse the admin console of Pi-Hole. It should be something like "http://RASPBERRY_PI_IP_ADDRESS/admin/".

Pi-Hole Statistics

On mine, it looks like this.. This statistic is after about less than an hour of having it installed. Do you have Pi-Hole installed? Share your story in the comments.

Share:

HOW-TO: Online Resizing of a MultiPath LUN

Online resizing of a multipath LUN is challenging. Try to wrap your head around the task at hand for a bit and understand the underlying principles behind this complex and challenging task. It is overwhelming! I have been in this particular scenario a lot and I know how it is to be on your shoes the first time.

But trust me, it may not be as daunting a task as you may think. Bear with me for a bit as I outline the steps needed to perform this task, successfully and without complications.

The previous article, Add LUNs to a Linux Host Without Reboot suggested the use of a well working script "rescan-scsi-bus.sh" via installation of the sg3_utils RPM. This task will do the same thing. So if this package is not installed, the script will probably be missing from your system as well. It would be a good idea to install it (yum -y install sg3_utils).

The first task on the list is to expand the LUN on the storage level. If you have an EMC storage, get to Unisphere and expand the LUN or the OnCommand System Manager for NetApp. On other storage systems, use the tools native to the storage to expand. Once that is done use rescan-scsi-bus.sh to rescan the LUNs.

For me (and some of you), "rescan-scsi-bus.sh -l" may already work. If not, use "rescan-scsi-bus.sh --forcerescan" to detect the new LUN sizes.

NOTE: The examples below will use the multipath device /dev/mpath/mpath165; and, /dev/sdat, /dev/sdh, /dev/sdap and /dev/sdd as its underlying devices. Its size is 190GB and we will add 100GB to it.

Next, check the devices relevant to the LUN. In this case -- mpath165. Change this with the multipath alias of your LUNs. Execute:

[root@vhost ~#] multipath -l mpath165
mpath165 (36006016098402e007cb4e6580ef1e311) dm-17 DGC,VRAID
[size=190G][features=1 queue_if_no_path][hwhandler=1 alua][rw]
  \_ round-robin 0 [prio=0][enabled]
   \_ 1:0:1:3 sdat 66:208 [active][undef]
   \_ 0:0:1:3 sdh  8:112  [active][undef]
  \_ round-robin 0 [prio=0][active]
   \_ 1:0:0:3 sdap 66:144 [active][undef]
   \_ 0:0:0:3 sdd  8:48   [active][undef]

The above output means there are four (4) paths composing the multipath device mpath165. They are /dev/sdat, /dev/sdh, /dev/sdap and /dev/sdd. The outputs on your system may vary.

Then, let the system detect the new size of the LUNs.

[root@vhost ~#] blockdev --rereadpt /dev/sdat
[root@vhost ~#] blockdev --rereadpt /dev/sdh
[root@vhost ~#] blockdev --rereadpt /dev/sdap
[root@vhost ~#] blockdev --rereadpt /dev/sdd
[root@vhost ~#] blockdev --getsz /dev/sdat
  608174080
[root@vhost ~#] blockdev --getsz /dev/sdh
  608174080
[root@vhost ~#] blockdev --getsz /dev/sdap
  608174080
[root@vhost ~#] blockdev --getsz /dev/sdd
  608174080

From the above commands, only getsz will provide an output. The outputs will be the same (due to the multipathing) and note them down for the commands we will execute later. If the outputs of "getsz" are not the same, something is wrong. Re-execute "blockdev --rereadpt" for that particular device.

Provided the outputs are all the same, proceed with the instructions below.

Next, dump the current multipath configuration and write the output to files -- mpath165.bak.
[root@vhost ~#] dmsetup table mpath165 | tee mpath165.bak
  0 398458880 multipath 1 queue_if_no_path 1 alua 2 2 round-robin 0 2 1 66:208 1000 8:112 1000 round-robin 0 2 1 66:144 1000 8:48 1000

Create a copy of the file "mpath165.bak" -- say "mpath165.new". Edit this file and replace the second number (398458880, which is the current size of the LUN) with the output of "blockdev --getsz" above.

(NOTE: Double check that the file mpath165.new has new values, where what used to be 398458880 should now be 608174080.)

This is the part where the LUN gets to be offline for a split second. It is imperative to stick these commands together. Or else..
[root@vhost ~#] dmsetup suspend mpath165; \
  dmsetup reload mpath165 mpath165.new ; \
  dmsetup resume mpath165

What actually happens in the above command is the multipath device mpath165 got suspended. Its configuration was replaced with the configuration contained in the file mpath165.new (or a resize was made). Then, the I/O operations were resumed. This was done quickly enough as if nothing happened.

Notify the kernel of a change of partition tables. Try partprobe first.
[root@vhost ~#] partprobe /dev/mpath/mpath165
-- or --
[root@vhost ~#] kpartx -a /dev/mpath/mpath165
[root@vhost ~#] kpartx -l /dev/mpath/mpath165

Now its time for LVM to take care of the rest of the resizing. When done right, this procedure can save you from unnecessary downtime due to multipath LUN resizing. Having known this procedure, resizing multipath LUNs will be just a routine for you.


Share:

HOW-TO: Add LUNs to a Linux Host Without Reboot

Abstraction between the operating system and the hardware is key to being able to modify running systems without having to reboot. Reboot is often associated with the dreaded word "downtime". This short downtime could cost some hundreds of dollars while for some, it could be in the magnitude of hundreds of thousands of dollars.

One of the major reasons for downtime is adding hardware to the host. And, more often than not, it is storage that is being added. Abstraction between the operating system and the hardware layer is key to planning and playing it out without causing or even costing the company downtime.

On the hardware layer, adding LUNs is a simple introduction or mapping of the drive to the host. This is the conventional way of doing it. Sad thing, however, it doesn't always work.

By conventional, I mean this method of rescanning the SCSI bus for a particular host.
echo "- - -" > /sys/class/scsi_host/host0/scan
The triple dashes "- - -" are wildcards that rescan every channel, every target, and every LUN on the specificed SCSI host. The above command scans the SCSI bus for new devices and map those drives to new device nodes that could be used by the Linux host. This works about 60-70% of the time. For the remaining 30-40%, I follow a better route that has flawlessly worked for me so far.

The utility or tool I use doesn't get installed by default. It is imperative that you have the original installation media or an internet connection for this to work.

For RHEL, Fedora and CentOS hosts, the command to run is:
yum -y install sg3_utils
The above command will likewise install dependent packages that it requires. The sg3_utils package contains a script named rescan-scsi-bus.sh. This is what is needed for the addition of LUNs or drives.

To detect or rescan new devices, invoke the script via "rescan-scsi-bus.sh -l". For SAN LUNs, what I found to have worked perfectly is "rescan-scsi-bus.sh --forcerescan". To get colored output the addition of "--color" makes all that possible.

This works for me whether the host is bare-metal or virtual.

RedHat warns about caveats for using sg3_utils scripts.

SG3 Known Issues

So far this tool has helped me avoid reboots and incurring the corresponding downtime. I hope it helps you as well.

Share:

ERROR: YUM -- Unfinished Transactions Remaining..

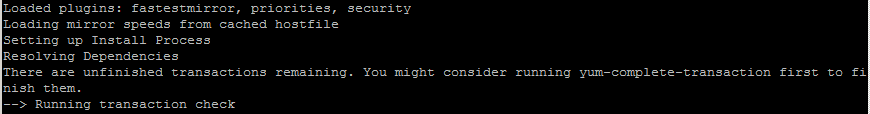
Linux is not perfect. Chances are when installing packages from repositories, some error will show up -- more commonly the conflict between packages. This prevents the install or update of the packages due to the conflicts. On rare occassions, there would be times when yum may fail to complete transactions. This is the time when you will see a similar error message as below:

There are unfinished transactions remaining. You might consider running yum-complete-transaction first to finish them.

.. or this screenshot with the error message..

yum-complete-transaction

Sometimes a modified version of the message appears in this manner:

There are unfinished transactions remaining. You might consider running yum-complete-transaction first to finish them.
The program yum-complete-transaction is found in the yum-utils package.

This latter message is a little bit more meaningful in that it gives you a clue that the executable "yum-complete-transaction" is supplied by the yum-utils rpm package. Install this rpm if required.

WARNING: Although yum itself is suggesting to run "yum-complete-transaction", do not run it. If you could avoid running it, do so. Running "yum-complete-transaction" without knowing what the previous transaction was may wipe out your whole system. It could be disastrous.

I know it is very inconvinient to have the error message show up in the yum transactions but if that is what's bothering you, take the safer mode and execute yum-complete-transaction with the argument "--cleanup-only". The exact command to execute is:

# yum-complete-transaction --cleanup-only

This way yum will never make any change to your system. Again, do not run yum-complete-transaction if you don't have a backup of your system. You may end up wiping the contents of your drive. I have seen this happen several times that I have learned my lesson -- from both my mistakes and the mistakes of others.

Share:

TIP: Taking Advantage of Virtual Hot Add Technology

As a system administrator, I could say virtualization is one of the best things that happened since sliced bread. This of course is in terms of utilization and the thin provisioning mechanism it entails. What usually happens is that, the guest operating system is tricked into believing that it has all that resource for itself; whereas, what actually happens is that it only is allocated a slice of it, and it will get the resource as necessary.

This is neat technology. The other side of the coin is that you may allocate a thick provisioned resource but at a fraction of its entirety. What does this mean? The short term -- skimping -- I use this when I can't estimate the exact requirement of an application. I rely on the "hot add" technology of virtualization to allocate the final pieces of the architecture when more accurate information is available. In the virtualization lingo, the terms "hot add" and "hot plug" are often used interchangably and likely pertain to the same thing.

Modern operating systems play a big role in this "hot add" technology. For example, in the Linux world once the application has been tested and it was later found to be CPU-bound, just hot add more cores. Not really that interesting, right? But wait, you can do this without having to reboot the virtual machine -- NO DOWNTIME! Adding virtual CPUs while it is running -- now that's cool stuff! This of course assumes that the hot add feature has been turned on.

This is how its done on the VMware side of things.

Enable Hot Add

The same can be done to memory -- once a guest is identified to be memory-bound -- just hot add more memory.

A recent experience taught me that this doesn't always work. It works for CPU hot plug, but for memory hot add it doesn't. I'm using the recent version of RHEL 6.4 x86_64 and CentOS 6.4 x86_64. Both of these operating systems don't work well with memory hot add, but their older versions used to work.

Executing a memory hot add on a RHEL/CentOS 6.4 guest, this error appears:

------------[ cut here ]------------
WARNING: at arch/x86/mm/init_64.c:701 arch_add_memory+0xe2/0x100() (Not tainted)
Hardware name: VMware Virtual Platform
Modules linked in: vsock(U) vmci(U) autofs4 sunrpc ipv6 ipt_REJECT ppdev parport_pc parport microcode vmware_balloon e1000 shpchp sg i2c_piix4 i2c_core ext4 mbcache jbd2 sd_mod crc_t10dif sr_mod cdrom mptsas mptscsih mptbase scsi_transport_sas pata_acpi ata_generic ata_piix dm_mirror dm_region_hash dm_log dm_mod [last unloaded: nf_conntrack]
Pid: 25, comm: kacpi_notify Not tainted 2.6.32-358.2.1.el6.x86_64 #1
Call Trace:
 [] ? warn_slowpath_common+0x87/0xc0
 [] ? warn_slowpath_null+0x1a/0x20
 [] ? arch_add_memory+0xe2/0x100
 [] ? add_memory+0xb7/0x1c0
 [] ? acpi_memory_enable_device+0x95/0x12b
 [] ? acpi_memory_device_add+0x118/0x121
 [] ? acpi_device_probe+0x50/0x122
 [] ? driver_probe_device+0xa0/0x2a0
 [] ? __device_attach+0x0/0x60
 [] ? __device_attach+0x0/0x60
 [] ? __device_attach+0x53/0x60
 [] ? bus_for_each_drv+0x64/0x90
 [] ? device_attach+0xa4/0xc0
 [] ? bus_probe_device+0x2d/0x50
 [] ? device_add+0x527/0x650
 [] ? pm_runtime_init+0xcb/0xe0
 [] ? device_register+0x1e/0x30
 [] ? acpi_add_single_object+0x837/0x9e8
 [] ? acpi_ut_release_mutex+0x63/0x67
 [] ? acpi_bus_check_add+0xe0/0x138
 [] ? acpi_os_execute_deferred+0x0/0x36
 [] ? acpi_bus_scan+0x3a/0x71
 [] ? acpi_bus_add+0x2a/0x2e
 [] ? acpi_memory_device_notify+0xa6/0x24f
 [] ? acpi_os_execute_deferred+0x0/0x36
 [] ? acpi_bus_get_device+0x2a/0x3e
 [] ? acpi_bus_notify+0x4b/0x82
 [] ? acpi_os_execute_deferred+0x0/0x36
 [] ? acpi_ev_notify_dispatch+0x64/0x71
 [] ? acpi_os_execute_deferred+0x29/0x36
 [] ? worker_thread+0x170/0x2a0
 [] ? autoremove_wake_function+0x0/0x40
 [] ? worker_thread+0x0/0x2a0
 [] ? kthread+0x96/0xa0
 [] ? child_rip+0xa/0x20
 [] ? kthread+0x0/0xa0
 [] ? child_rip+0x0/0x20
---[ end trace 081e3b980cb5c943 ]---
ACPI:memory_hp:add_memory failed
ACPI:memory_hp:Error in acpi_memory_enable_device
acpi_memhotplug: probe of PNP0C80:00 failed with error -22

 driver data not found
ACPI:memory_hp:Cannot find driver data

You will see the above error message when the command "dmesg" is executed on a terminal window. This seems to be a bug in the kernel module for memory hot add.

This is a bug that I hope gets fixed in future versions of the Linux kernel. If you rely on memory hot add feature, please be aware of this limitation on the new versions of RHEL and CentOS. It seems to be rooted to the kernel code so most likely all other flavors of Linux are in the same boat.

The Windows operating system doesn't seem to have this problem. Hot plug of virtual CPUs and hot add of memory works without any problem.

Share:

TIP: Linux Virtual Machine Performance Tweaks

The advent of virtualization, changed many rules of technology -- what may apply to the physical world could be detrimental to its virtual equivalent. This is likewise true in terms of performance. Optimizing the performance of one virtual machine impacts the performance of others. In the end, tweaking for performance not only pays off big time, but does that in magnitudes of two-, three-fold or even more.

The above statements are true due to sharing of resources in the hypervisor level. If resources are freed by performance tweaks, it makes them available to others waiting for the same resource to be available for use.

The first of these tweaks is to ensure that the disk used by the virtual machine is aligned. Why is this important? To better understand the underlying infrastructure of the virtual filesystem, refer to the screenshot. (Illustration from http://www.yellow-bricks.com)


As seen from the diagram, the misalignment of the array, to the virtual filesystem, and, to the guest disk is very, very significant. A big performance degradation will occur due to the misalignment. What happens here is that, what could be seen as a single I/O operation on the guest operating system could end up as multiple I/O operations on the physical disk or array.

Translate the above performance degradation to multiple virtual machines and you see the drift. According to VMware (Reference):
The degree of improvement from alignment is highly dependent on workloads and array types. You might want to refer to the alignment recommendations from your array vendor for further information. 

Still, I/O could be a potential performance bottleneck if the disk alignment is not kept in check.

While on the same topic of I/O bottlenecks, Linux virtual machines could benefit from the proper I/O scheduler. Again, this is another arena where the physical rules and virtual rules differ.

Modern Linux kernels default to the "completely fair queuing" (or CFQ) scheduler. This is how the kernel deals with optimizing I/O. It re-orders I/O in such a manner that when the head moves across the platter, it does that in an orderly, sequential manner rather than moving back and forth to complete requests. The best illustration to this is an elevator, where it drops people to floors in an orderly sequential manner. Instead of dropping passengers as they push the corresponding floor buttons, what happens is the elevator drops people off at 2, then 5, then 6, before going to 11. The kernel has different methods of doing this.


Imagine that the hypervisor has its own elevator, the guest has its own elevator and the array has its own. When the guest performs that optimization, the hypervisor does the same, and the array does the same. Who then decides what is the best re-ordering or optimization? The hypervisor has no insight on the guest operating system (this time a Linux machine), meaning it can't tell the method used for optimization, or how they got re-ordered, if they indeed got re-ordered or why it came to that decision.

This kernel optimization has no impact on the virtual environment and in some situations could have a negative effect. Why? The hypervisor has no way of telling how long an I/O has been outstanding or how it got re-ordered and why it was that way on the guest level. Add the hypervisor elevator and that adds further latency to the already outstanding I/O request.

It would be best to leave all optimizations on the hypervisor level and turn off the elevator on the kernel level. This is done by having the string "elevator=noop" on the kernel line of the grub.conf file of Linux. The other way of turning it off is by choosing the noop scheduler, as recommended by VMware.

This is the default setting.
# cat /sys/block/[DEVICE]/queue/scheduler
noop deadline anticipatory [cfq]
Change it for every [DEVICE].
# echo noop > /sys/block/[DEVICE]/queue/scheduler
# cat /sys/block/[DEVICE]/queue/scheduler
[noop] deadline anticipatory cfq

If you have screensavers running, those are detrimental to the performance of virtual machines. Disable them at once. I have seen a virtual machine with a load of 5.0 reduced to 0.0 simply by disabling the screensaver!

The other tweak you could perform is to change to runlevel 3. Running on a GUI (runlevel 5), consumes a lot of resources that would otherwise be free if running at runlevel 3.

Permanently change it on the file /etc/inittab.
id:3:initdefault

By tweaking, you squeeze the best performace out of your current infrastructure and free up resources otherwise sapped by useless unnecessary processes or simple misconfigurations. The combination of the tweaks above may yield better results than applying one tweak alone.

Share:

FAQ: Cloned Linux Virtual Machine with Boot Errors

Q. While working on a few cloned RHEL virtual machines just a few days ago, I encountered a weird error that almost stopped me dead on my tracks. I was expecting the tasks to be a breeze since cloning via virtual machine templates is as easy as click, click, click.

As it turned out, what was supposedly a few clicks was more complex than what I thought. The clone virtual machines simply refused to boot. To give you a better understanding of the error see the screenshot below.


Opening the console of the virtual machine, the repeated errors prompted are:
vmsvc[xxx]: [ warning] [guestinfo] RecordRoutingInfo: Unable to collect IPV4 routing table.

The messages above are repeated at about every minute.. And, worse, the boot sequence is stuck at this phase and will not proceed.

After exhausting my patience waiting for the host to boot up, I gave up and resorted to shutting down the virtual machines to figure out what was wrong. The VMware logs didn't give a clue what was wrong. Even RedHat forums didn't have information regarding the error.

What was striking was the "vmsvc" string, indicating this was somewhat VMware configuration related or a service related to VMware. This was happening to a RHEL Linux virtual machine. So I tried a different flavor of Linux -- CentOS. Same result. But for Windows Server 2003, it was not.

Google search came out with this same exact error message on the VMware Knowledge Base (KB #2048572). Executing the procedure in the resolution part did not help either.

It only applied when the guest operating system's time is ahead of the host. But that gave me a further clue -- how about if the time of the cloned guest is too far off from the host ESXi host? (Afterall it was converted to a template a while back. And it was not selective, as every cloned machine displayed this manifestation.)

It turned out this was the case. I decided to disable time synchronization completely between the host ESXi and guest RHEL virtual machine.. Bingo error gone.

A. To completely disable the time sync between the host ESXi hypervisor and the guest RHEL virtual machine, simply shutdown or power off the guest virtual machine and edit the .vmx configuration file. Add the following lines, if they don't exist:
tools.syncTime = "0"
time.synchronize.continue = "0"
time.synchronize.restore = "0"
time.synchronize.resume.disk = "0"
time.synchronize.shrink = "0"
time.synchronize.tools.startup = "0"
time.synchronize.tools.enable = "0"
time.synchronize.resume.host = "0"

It helps to enable SSH on the ESXi server and use vi to make changes to the guest .vmx file. After adding the above lines, problem was solved and subsequent clones were easier.

The only task left to be done was to convert the template to a VM, make the same changes and re-template. This was a very fruitful learning experience.

Share:

INFO: RHEL Cluster -- Luci Installation Error

I have had the chance of administering and maintaining several implementations of Red Hat Cluster, but I never really had the chance to build one from scratch. So a chance presented itself recently and I bumped into several unforgettable experiences along the way. It roused my inquisitive nature and fruitful learnings were gleaned off the obstacles. One of them was with the initial install of luci (and ricci).

The easiest way to configure a Red Hat Cluster is via luci (and ricci), especially for a RHEL Cluster noob like me. I couldn't argue with that statement. It is easier, although I would love to go a little deeper and understand the command line equivalents of the web based configurations done. So I got to install luci after configuring ricci.

To initialize the luci configuration, I ran this command:
[root@vhost ~]# /usr/bin/paster make-config luci /var/lib/luci/etc/luci.ini --no-default-sysconfig --no-install

However, the result was not as expected. And a configuration file was not created. The errors are below:
[root@vhost ~]# /usr/bin/paster make-config luci /var/lib/luci/etc/luci.ini --no-default-sysconfig --no-install
Distribution already installed:
  luci 0.26.0 from /usr/lib/python2.6/site-packages
Traceback (most recent call last):
  File "/usr/bin/paster", line 9, in 
    load_entry_point('PasteScript==1.7.3', 'console_scripts', 'paster')()
  File "/usr/lib/python2.6/site-packages/paste/script/command.py", line 84, in run
    invoke(command, command_name, options, args[1:])
  File "/usr/lib/python2.6/site-packages/paste/script/command.py", line 123, in invoke
    exit_code = runner.run(args)
  File "/usr/lib/python2.6/site-packages/paste/script/appinstall.py", line 68, in run
    return super(AbstractInstallCommand, self).run(new_args)
  File "/usr/lib/python2.6/site-packages/paste/script/command.py", line 218, in run
    result = self.command()
  File "/usr/lib/python2.6/site-packages/paste/script/appinstall.py", line 295, in command
    self.distro, self.options.ep_group, self.options.ep_name)
  File "/usr/lib/python2.6/site-packages/paste/script/appinstall.py", line 234, in get_installer
    'paste.app_install', ep_name)
  File "/usr/lib/python2.6/site-packages/pkg_resources.py", line 2229, in load_entry_point
    return ep.load()
  File "/usr/lib/python2.6/site-packages/pkg_resources.py", line 1947, in load
    if require: self.require(env, installer)
  File "/usr/lib/python2.6/site-packages/pkg_resources.py", line 1960, in require
    working_set.resolve(self.dist.requires(self.extras),env,installer))
  File "/usr/lib/python2.6/site-packages/pkg_resources.py", line 550, in resolve
    raise VersionConflict(dist,req) # XXX put more info here
pkg_resources.VersionConflict: (WebOb 0.9.6.1 (/usr/lib/python2.6/site-packages), Requirement.parse('WebOb>=0.9.7'))

The "python-webob-0.9.6.1-3.el6.noarch" RPM was properly installed but it looks like the package it is looking for is versions higher. As checked, the python-webob package available is already installed.

I also tried several versions of python-webob packages from several known repositories. Only to fail with the same errors above.

It turns out the "python-repoze-who-friendlyform.noarch" package is in conflict with other repositories. When installing luci, install from the base repository only. Disable EPEL and other enabled repositories.

[root@vhost ~]# yum -y install luci
Loaded plugins: fastestmirror, security
Loading mirror speeds from cached hostfile
Setting up Install Process
Resolving Dependencies
--> Running transaction check
---> Package luci.i686 0:0.26.0-37.el6.centos will be installed
--> Processing Dependency: python-repoze-who-friendlyform for package: luci-0.26.0-37.el6.centos.i686
--> Running transaction check
---> Package python-repoze-who-friendlyform.noarch 0:1.0-0.3.b3.el6 will be installed
--> Finished Dependency Resolution

Dependencies Resolved

============================================================================================================
 Package                                 Arch            Version                        Repository     Size
============================================================================================================
Installing:
 luci                                    i686            0.26.0-37.el6.centos           base          553 k
Installing for dependencies:
 python-repoze-who-friendlyform          noarch          1.0-0.3.b3.el6                 base           13 k

Transaction Summary
============================================================================================================
Install       2 Package(s)

Total download size: 566 k
Installed size: 2.2 M
Downloading Packages:
(1/2): luci-0.26.0-37.el6.centos.i686.rpm                                            | 553 kB     00:00 ... 
(2/2): python-repoze-who-friendlyform-1.0-0.3.b3.el6.noarch.rpm                      |  13 kB     00:00 ... 
------------------------------------------------------------------------------------------------------------
Total                                                                       4.9 MB/s | 566 kB     00:00     
Running rpm_check_debug
Running Transaction Test
Transaction Test Succeeded
Running Transaction

  Installing : python-repoze-who-friendlyform-1.0-0.3.b3. [                                           ] 1/2
  Installing : python-repoze-who-friendlyform-1.0-0.3.b3. [##                                         ] 1/2
  ...
  Installing : python-repoze-who-friendlyform-1.0-0.3.b3. [########################################## ] 1/2
  Installing : python-repoze-who-friendlyform-1.0-0.3.b3.el6.noarch                                     1/2 
  Installing : luci-0.26.0-37.el6.centos.i686 [                                                       ] 2/2
  Installing : luci-0.26.0-37.el6.centos.i686 [#                                                      ] 2/2
  ...
  Installing : luci-0.26.0-37.el6.centos.i686 [###################################################### ] 2/2
  Installing : luci-0.26.0-37.el6.centos.i686                                                           2/2 

  Verifying  : luci-0.26.0-37.el6.centos.i686                                                           1/2 
  Verifying  : python-repoze-who-friendlyform-1.0-0.3.b3.el6.noarch                                     2/2 

Installed:
  luci.i686 0:0.26.0-37.el6.centos                                                                          

Dependency Installed:
  python-repoze-who-friendlyform.noarch 0:1.0-0.3.b3.el6                                                    

Complete!
[root@vhost ~]# /usr/bin/paster make-config luci /var/lib/luci/etc/luci.ini --no-default-sysconfig --no-install
Distribution already installed:
  luci 0.26.0 from /usr/lib/python2.6/site-packages
/usr/lib/python2.6/site-packages/tw/core/view.py:223: DeprecationWarning: object.__new__() takes no parameters
  obj = object.__new__(cls, *args, **kw)
Creating /var/lib/luci/etc/luci.ini
Now you should edit the config files
  /var/lib/luci/etc/luci.ini
[root@vhost ~]# service luci start
Adding following auto-detected host IDs (IP addresses/domain names), corresponding to `host.localdomain' address, to the configuration of self-managed certificate `/var/lib/luci/etc/cacert.config' (you can change them by editing `/var/lib/luci/etc/cacert.config', removing the generated certificate `/var/lib/luci/certs/host.pem' and restarting luci):
(none suitable found, you can still do it manually as mentioned above)

Generating a 2048 bit RSA private key
writing new private key to '/var/lib/luci/certs/host.pem'
[  OK  ]
Start luci...
Point your web browser to https://host.localdomain:8084 (or equivalent) to access luci

So after reinstalling the luci package from the base repo (from the ISO itself), I was able to successfully initialize luci and continue with the cluster configuration.


Share:

HOW-TO: Kill Zombie Processes with Parent ID (PID) of 1

As a system administrator, we are often briefed on the careful use of the "kill" command. Indeed to use this command, you need to know what you're doing.. you really really need to know what you're doing. Seasoned system administrators would often talk about the first time they used this command and the racing heart rate before hitting the execute key.

It's not that bad though. Like all critical things this command could be the "last-resort" tool you need to resolve a complex issue -- in case of fire break glass thing, sort of. But the "kill" command doesn't always work. I'd say about 99% of the time it will. You need to be a seasoned system administrator long enough to encounter this problem as it doesn't come along very often.

I decided to post this solution since last week, I encountered a runaway samba (smbd) process. Samba had to be stopped but instead of it gracefully shutting down, only the parent process did and left behind a lot of child processes. They in turn became zombie processes -- about 257 of them.

It would not have mattered much, but the load on the server increased to match the number of zombie processes. In a matter of seconds, it became a critical problem that need to be dealt with. To illustrate the criticality of the situation, here are a couple of indicators.

[root@vhost ~]# ps -ef | grep smbd | wc -l
257
[root@vhost ~]# uptime
15:18:09 up 95 days,  5:04,  6 users,  load average: 257.91, 257.98, 255.54

When ps is executed, it returned smbd processes that had a parent ID (PID) of 1 -- zombie processes.

[root@vhost ~]# ps -ef | grep smb | tail
nobody   31590     1  0 12:29 ?        00:00:00 smbd -D
nobody   31705     1  0 11:55 ?        00:00:00 smbd -D
nobody   31743     1  0 14:31 ?        00:00:00 smbd -D
nobody   32049     1  0 12:19 ?        00:00:00 smbd -D
nobody   32415     1  0 12:04 ?        00:00:00 smbd -D
nobody   32484     1  0 14:25 ?        00:00:00 smbd -D
nobody   32508     1  0 13:35 ?        00:00:00 smbd -D
nobody   32511     1  0 12:04 ?        00:00:00 smbd -D
nobody   32535     1  0 13:22 ?        00:00:00 smbd -D
nobody   31599     1  0 11:51 ?        00:00:00 smbd -D
[root@vhost ~]# kill -9 31599

Killing any of the smbd processes didn't do much. Server load is holding steady at 257 and none of the smbd processes get terminated.

Once a process becomes a zombie process (or with a PID of 1), there is no amount of "kill" that could terminate it. The only other known way to terminate the zombie process is to do a host reboot. You and I both know this is to be avoided as much as possible.

The other way to do it is not known to many. Only a handful of system administrators that I personally know, knew how to use this command. The command is "telinit". This is the alternative to rebooting the server. To kill the zombie process(es) or processes with PID of 1, execute "telinit u" or "telinit U". Executing the command "telinit u" makes init (the process with ID 1) restart, or as the man pages state it, re-execute, without having to reboot the host.

Once this was done, an immediate impact of decrease in server load was felt. Also, the smbd processes that used to be zombies are now gone.

[root@vhost ~]# uptime
15:21:22 up 95 days,  5:07,  6 users,  load average: 49.06, 184.80, 229.74

About 5 minutes after execution of telinit. The load has re-stabilized.

So if a fellow administrator asks you if you know how to kill a zombie process, let them know that you belong to those handful of seasoned system administrators who don't consider reboot a solution to terminate a zombie process.

I have asked this question in several interviews so far only a few got it right. And I consider it major point in hiring.


Share:

HOW-TO: Prep Work for Linux P2V (Physical to Virtual)

Virtualization is the technology trend that is "in" nowadays. It is debatable whether the money you save in hardware costs (and other variable costs) can equate or best the savings of whatever virtualization technology deployed or implemented. But that is beyond the point of this article.

Physical to virtual (otherwise known as P2V) is the process of converting a baremetal host to a virtual equivalent. For Linux hosts, there is only one way to do this. P2V is done from a Windows host that has the VMware Standalone Converter installed. The best way to do this without downtime is to do your homework prior to. Prep work is vital in a production environment.

The quickest way to avoid downtime is to choose to shutdown the physical machine and boot the virtual machine when conversion (or P2V) is done. This is via checking a tick box during the conversion process. However, in my experience the virtual machine doesn't always boot after the conversion. How then do we ensure that the virtual machine boots up after conversion?

One key strength of VMware is its virtual machines (and their corresponding drivers) are assigned or given a generic set of hardware. The hardware on the VMs are as generic as possible for maximum compatibility. This enables the VM to migrate (or vMotion) to compatible architectures with least impact or even no impact at all. The end-user will not even feel the vMotion occur or experience any glitch while the machines migrate from one ESXi host to the other. While a continuous ping is done it might drop one or two packets while a vMotion is going on but that really is not felt by the user most of the time.

Given the above, one way to ensure a successful P2V is that hardware specific limitations do not exist on the virtual machine (or VM). What then are hardware specific limitations? The MAC address is one. Virtual machines are automatically assigned a different MAC address than the one on the physical host. If the MAC address is hard-wired, then obviously the resulting Linux VM will not like it.

On Fedora flavors of Linux as well as its Community operating system counterpart, there are two locations where the MAC address is hard-wired or hard-coded. The file /etc/udev/rules.d/70-persistent-net.rules contain the hard-coded MAC address. As seen from the screenshot below, the host has two (2) network interface cards, and CentOS has detected them all and assigned them names eth0 and eth1. Their corresponding MAC addresses are also listed. This way the OS knows which NIC is assigned what name.


Sometimes, the files ifcfg-eth0, ifcfg-eth1 -- located in /etc/sysconfig/network-scripts -- also contain the hard-coded MAC addresses. This is another way for the OS to know the particular NIC has been assigned a corresponding device name. Below are entries for the file ifcfg-eth0.


On both of the above scenarios, you may choose to delete the lines containing the MAC addresses or place a hash (#) in the beggining of the line to make the OS ignore them.

Other times, the VM refuses to boot due to a missing module in the initrd file. And the solution could vary between scenarios. Still, it helps to do your homework prior to so you can minimize downtime and anticipate headaches that may come your way.


Share:

HOW-TO: Confirm Free Memory Slots on your Server (Linux)

Often times, we system administrators let our fingers do the walking.. sometimes, literally. This is true for just about every activity involving administration. The only time when the system administrator meets face to face with the physical hardware they administer is when they need to replace failed parts or when upgrading hardware.

Upgrading though needs a few pre-requisites that need to be planned out in advance. Memory upgrades being an example, one needs to know what kind of memory is installed on the server, and if there are free memory slot(s). The last mentioned being a very important tidbit of information. A memory upgrade is not possible without free memory slots. This is a major gotcha that you need to avoid.

In the Linux world, this can be done in many ways. Let's discuss two of the more commonly used commands -- dmidecode and lshw.

Using dmidecode. Almost every linux box I have administered came with dmidecode installed by default. It is a rare encounter to find a box without dmidecode installed.

Launch a command terminal and run "sudo dmidecode --type memory". Running dmidecode by itself will spew out a lot of information regarding your machine. Putting the arguments "--type memory", singles out memory devices, keeping the needed info only.

Another argument that will limit the output to just memory listing is "-t 17". These commands will be showing a similar output as below.

dmidecode memory slot populated

As you can see from the above example, DIMM Slot #1 is populated with a 2GB DDR2-800 module. Even the part number and serial of the memory module is detected.

How about when the slot is empty? Take a look at the screenshot below for the output of dmidecode when a slot is empty.

dmidecode memory slot empty

Using lshw. Another very useful command is lshw. It will display all the installed hardware on the system. And just like dmidecode, you may choose to run it only to display or single out memory devices.

Launch a command prompt and run "sudo lshw". Adding "-C memory" or "-class memory" will limit the display to just the memory slots and modules.

lshw class memory

There you go, plan the memory upgrades properly given the above commands. They ensure not only having empty memory slots to fill, but also display the proper memory module to install. Given the above information, you can never go wrong with the upgrade.

Share:

FAQ: Error Rebuilding sendmail.cf

"There’s No Such Thing As A Silly Question" -- does the cliche sound familiar? In this part of pimp-my-rig reloaded, technical questions are answered. Mail them to me and I will post the answers here. If you have a better answer, by all means share it with us.

Guides on the net suggest that you do not edit sendmail.cf by hand. First, make changes to sendmail.mc then rebuild sendmail.cf using the command: "m4 sendmail.mc > sendmail.cf". However, this command sometimes fails and before you know it you have unknowingly made changes to sendmail.cf -- the file is now 0 bytes. The error message is below:

[root@host mail]# m4 sendmail.mc > sendmail.cf
sendmail.mc:10: m4: cannot open `/usr/share/sendmail-cf/m4/cf.m4': No such file or directory

Things are pretty simple if you look at the error.. but it is very deceiving. Take a look at your sendmail.cf.

[root@host mail]# ls -la sendmail.cf
-rw-r--r-- 1 root root 0 Feb 18 10:02 sendmail.cf
Ooppss.. sendmail.cf is now zero bytes. You can rebuild sendmail.cf from sendmail.mc using m4, but you just executed the exact command to re-generate sendmail.cf ending in errors. Re-starting sendmail will make things worse. Sendmail will still work as it read sendmail.cf before the error. Restarting it will re-read the zeroed out sendmail.cf file.

I got stuck in this error before. And a colleague got stuck in it just recently.

The guides either forgot to mention that or assumed that it is installed and you will need to have installed the sendmail-cf rpm. How do you know that sendmail-cf is the required rpm? Take a closer look at the first few lines of sendmail.mc.

[root@host mail]# head sendmail.mc
divert(-1)dnl
dnl #
dnl # This is the sendmail macro config file for m4. If you make changes to
dnl # /etc/mail/sendmail.mc, you will need to regenerate the
dnl # /etc/mail/sendmail.cf file by confirming that the sendmail-cf package is
dnl # installed and then performing a
dnl #
dnl #     make -C /etc/mail
dnl #

So what you can do now is install sendmail-cf rpm.

[root@host mail]# yum -y install sendmail-cf
Loaded plugins: fastestmirror
Loading mirror speeds from cached hostfile
 * base: mirror.web.com.ph
 * extras: mirror.web.com.ph
 * updates: mirror.web.com.ph
Setting up Install Process
Resolving Dependencies
--> Running transaction check
---> Package sendmail-cf.x86_64 0:8.13.8-8.1.el5_7 set to be updated
--> Finished Dependency Resolution

Dependencies Resolved

================================================================================
 Package            Arch          Version                  Repository      Size
================================================================================
Installing:
 sendmail-cf        x86_64        8.13.8-8.1.el5_7         updates        306 k

Transaction Summary
================================================================================
Install       1 Package(s)
Upgrade       0 Package(s)

Total download size: 306 k
Downloading Packages:
sendmail-cf-8.13.8-8.1.el5_7.x86_64.rpm                  | 306 kB     00:00
Running rpm_check_debug
Running Transaction Test
Finished Transaction Test
Transaction Test Succeeded
Running Transaction
  Installing     : sendmail-cf                                              1/1

Installed:
  sendmail-cf.x86_64 0:8.13.8-8.1.el5_7

Complete!

Now re-run "m4 sendmail.mc > sendmail.cf" and it will be error free. You can safely make changes to sendmail.mc and generate sendmail.cf from that.

Share:

HOW-TO: Unload nouveau and Install Nvidia Driver

If you have installed Linux on a machine with Nvidia graphics cards, Linux (Red Hat based ones) would likely default to installing the nouveau video driver for that graphics card. It is a challenge to unload the driver and install the Nvidia graphics drivers to properly display the desktop environment.

As you can see from the output of lsmod below, there are a lot of dependencies to the nouveau driver.

[root@host ~]# lsmod | grep nouveau
Module                  Size  Used by
nouveau               639801  1 
ttm                    57516  1 nouveau
drm_kms_helper         28144  1 nouveau
drm                   185516  3 nouveau,ttm,drm_kms_helper
i2c_algo_bit            4690  1 nouveau
i2c_core               25825  5 i2c_i801,nouveau,drm_kms_helper,drm,i2c_algo_bit
mxm_wmi                 1473  1 nouveau
video                  16720  1 nouveau

The nouveau driver needs to be uninstalled before the Nvidia drivers can be installed. Installing the Nvidia drivers for Linux without removing nouveau will result in errors. Trying to unload and remove the driver is not that easy.

[root@host ~]# rmmod nouvueau
ERROR: Module nouveau is in use

And as you can see from the output of the above rmmod command, it resulted in an error. How then do you install the Nvidia drivers if nouveau could not be uninstalled?

I followed the steps below to unload nouveau and install the Nvidia driver for my workstation's video card. This procedure was taken from http://nouveau.freedesktop.org/wiki/KernelModeSetting.

[root@host ~]# echo 0 > /sys/class/vtconsole/vtcon1/bind
[root@host ~]# rmmod nouveau
[root@host ~]# /etc/init.d/consolefont restart
-bash: /etc/init.d/consolefont: No such file or directory
[root@host ~]# rmmod ttm
[root@host ~]# rmmod drm_kms_helper
[root@host ~]# rmmod drm

I was now able to install the Nvidia drivers. However, when I rebooted the machine, the nouveau drivers were still loaded even though the Nvidia drivers were already installed.

You will need to prevent the nouveau drivers from loading at boot-time. You can do this two-ways:

[1] Create the blacklist file inside the /etc/modprobe.d/ directory. This can be any arbitrary file as long as it is inside that directory. For the sake of easy administration, let us name this file "nouveau.conf". Put the following files:

blacklist nouveau
options nouveau modeset=0

and/or;

[2] If in case the ramdisk image contains the nouveau drivers, disable it at boot-time. Add the following phrase to your /etc/grub/grub.conf (on the kernel line):

rdblacklist=nouveau

The other alternative would be to rebuild the initrd image without the nouveau drivers.

 RELATED: Quantifiably Measure Boot Time Optimizations

After making the above changes to my CentOS 6.1 workstation, Nvidia drivers were loaded and I had things going for me. I hope this helps those who have difficulty in unloading and removing nouveau drivers.

Share:

INFO: What is a "Sticky Bit"?

At a recent job interview, I was asked this question. I was able to satisfactorily answer the question but failed to answer the follow-up question -- what is the difference between the sticky bit "t" (small letter) and the sticky bit "T" (bold letter)? This experience led me to improve my knowledge further. This post is dedicated to the experience I had, and to share the knowledge to those who quest for it.

What is the "Sticky Bit"? ("t" and "T"). The sticky bit is primarily used on shared directories with open permissions, such as /var/tmp and /tmp. Directories with open permissions (or publicly writable) present a lot of problems because users **CAN CREATE** files, **READ/EXECUTE** files owned by other users, and at the same time are **ALLOWED EDIT/REMOVE** privileges to files owned by other users.

With sticky bit set on publicly writable directories, users **CAN CREATE** files, **READ/EXECUTE** those files as well as files owned by other users, but are **NOT ALLOWED EDIT/REMOVE** privileges to files they don't own. The only exception to this is the super-user root which can edit or remove files.

In simple terms, sticky bit is used to indicate special treatment of certain directories. A directory for which the sticky bit is set restricts deletion or modification of files it contains. A file in a sticky bit set directory may only be removed, modified or renamed by a user who has write permission on the directory, and either owns the file, owns the directory, or is the super-user. This is useful for directories such as /tmp, which must be publicly writable, but should deny users permission to arbitrarily delete or rename the files of others.

It is worthy to note here that the directories with open permissions (or publicly writable) can be any arbitrary directory, not just limited to /tmp and /var/tmp. Its just that /tmp and /var/tmp exist by default on the system.

Which directory has sticky permissions? How do you identify a directory that has sticky bit set? To illustrate further see the example below.

user@host# ls -ld /sticky/directory
drwxrwxrwt  2   user   group   512   Jun 20 11:02  /sticky/directory

On the output of the "ls" command, see the "t" (on drwxrwxrwt)? That tells us that the sticky bit is set.
A "T" refers to when the execute permissions are OFF.
A "t" refers to when the execute permissions are ON.

How to set sticky bit permissions. The leading "1" in the "chmod" command sets the sticky bit.
user@host# chmod 1777 /sticky/directory (permissions for "other" have execute bit ON) 
drwxrwxrwt
user@host# chmod 1776 /sticky/directory (permissions for "other" have execute bit OFF)
drwxrwxrwT

The equivalent of the above commands in another syntax.
user@host# chmod o+t /sticky/directory
user@host# chmod o+x /sticky/directory
drwxrwxrwt        
user@host# chmod o+t /sticky/directory
user@host# chmod o-x /sticky/directory
drwxrwxrwT
Or..
user@host# chmod o=rwxt /sticky/directory
drwxrwxrwt        
user@host# chmod o=rwt /sticky/directory
drwxrwxrwT

There you go, more information regarding sticky bit. To my knowledge, sticky bit for files are not supported by any modern implementation of Unix or Linux. It is only significant and applicable to directories.

Share:

HOW-TO: Tabbed Putty with PuttyCM (Windows 7)

If you work as a system administrator and your workstation has windows (particularly Windows 7), chances are you connect to the Linux, Solaris, AIX or whatever flavor of *nix using putty. If by any chance you don't you might want to try putty, instead of the current program you're using.

I have used putty since I started working as a Unix sysad. And I can tell that putty in itself is a superb and versatile tool. But work starts getting complicated once you have several putty sessions open. And it becomes even challenging once you open more putty sessions. PuttyCM (or Putty Connection Manager) organizes putty sessions into tabs or split windows (by dragging a tab). This way, working becomes organized and much faster. You may want to download PuttyCM to try it out.

However, PuttyCM doesn't work out-of-the-box in Windows 7. So here's a pimp-my-rig feature designed to guide you in configuring PuttyCM to make it work in Windows 7. To give you a better understanding of what I mean by it doesn't work, here is the screenshot of PuttyCM connecting to my Popcorn Hour C-200 NMJ.

Tabbed Putty with PuttyCM (Windows 7)

As you can see, it doesn't work well. You are able to use the connection manager or putty sessions but it doesn't display the connection properly. And you can't do your job with PuttyCM. So it is just back to plain Putty or so it seems.

Here's how to make PuttyCM work in Windows 7.

Explore to the directory containing the PuttyCM executable (its filename is: puttycm.exe). Right-click the executable file and go to Compatibility tab. Choose compatibility for Windows Vista. You may choose Vista SP1 or SP2 as these work as well. Toward the bottom of the Compatibility tab, tick "Run this program as an administrator". You will be seeing a window similar to the one below.

Tabbed Putty with PuttyCM (Windows 7)

Now try to launch PuttyCM and connect to a host.

How sweet it is to see the terminal connection display.

Tabbed Putty with PuttyCM (Windows 7)

So there you go folks, working tabbed putty with PuttyCM in Windows 7. As of this writing, PuttyCM version 0.7.1 build 136 (beta) works. And the current alpha 0.7.1 build 233 works in Windows 7 and Windows 7 SP1.

Share:

Subscribe for Latest Update

Popular Posts

Post Labels

100gb (1) acceleration (1) acrobat (1) adblock (1) advanced (1) ahci (1) airdrop (2) aix (14) angry birds (1) article (21) aster (1) audiodg.exe (1) automatic (2) autorun.inf (1) bartpe (1) battery (2) bigboss (1) binance (1) biometrics (1) bitcoin (3) blackberry (1) book (1) boot-repair (2) calendar (1) ccleaner (3) chrome (5) cloud (1) cluster (1) compatibility (3) CPAN (1) crypto (3) cydia (1) data (3) ddos (1) disable (1) discount (1) DLNA (1) dmidecode (1) dns (7) dracut (1) driver (1) error (10) esxi5 (2) excel (1) facebook (1) faq (36) faucet (1) firefox (17) firewall (2) flash (5) free (3) fun (1) gadgets (4) games (1) garmin (5) gmail (3) google (4) google+ (2) gps (5) grub (2) guide (1) hardware (6) how (1) how-to (45) huawei (1) icloud (1) info (4) iphone (7) IPMP (2) IPV6 (1) iscsi (1) jailbreak (1) java (3) kodi (1) linux (28) locate (1) lshw (1) luci (1) mafia wars (1) malware (1) mapsource (1) memory (2) mikrotik (5) missing (1) mods (10) mouse (1) multipath (1) multitasking (1) NAT (1) netapp (1) nouveau (1) nvidia (1) osmc (1) outlook (2) p2v (2) patch (1) performance (19) perl (1) philippines (1) php (1) pimp-my-rig (9) pldthomedsl (1) plugin (1) popcorn hour (10) power shell (1) process (1) proxy (2) pyspark (1) python (13) qos (1) raspberry pi (7) readyboost (2) reboot (2) recall (1) recovery mode (1) registry (2) rename (1) repository (1) rescue mode (1) review (15) right-click (1) RSS (2) s3cmd (1) salary (1) sanity check (1) security (15) sendmail (1) sickgear (3) software (10) solaris (17) squid (3) SSD (3) SSH (9) swap (1) tip (4) tips (42) top list (3) torrent (5) transmission (1) treewalk (2) tunnel (1) tweak (4) tweaks (41) ubuntu (4) udemy (6) unknown device (1) updates (12) upgrade (1) usb (12) utf8 (1) utility (2) V2V (1) virtual machine (4) VirtualBox (1) vmware (14) vsphere (1) wannacry (1) wifi (4) windows (54) winpe (2) xymon (1) yum (1) zombie (1)

RANDOM POSTS